Do You Think You Have Enough Data for Artificial Intelligence?
As manufacturers begin to integrate AI solutions into their production lines, data scarcity has become a major challenge. Unlike consumer internet companies that have data from billions of users to build powerful AI models, collecting large training datasets in production is often not possible.
For example, in automotive manufacturing, where 6 Sigma practices are widely adopted, most OEMs and Tier 1 suppliers strive to have fewer than three to four defective parts per million parts. The rarity of these errors makes it difficult to have enough defective product data to train visual inspection models.
In a recent MAPI (Manufacturers Alliance for Productivity and Innovation) survey, 58% of survey respondents reported that the most significant barrier to the proliferation of AI solutions was a lack of data sources.
For example, how much data must be defined for artificial intelligence to identify an airplane image?
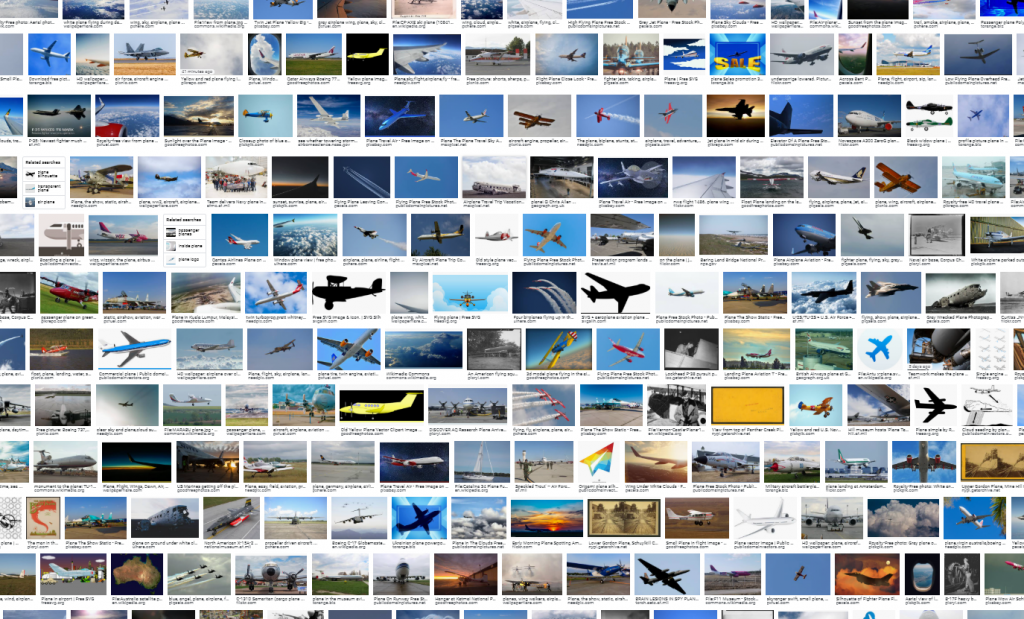
How much data must artificial intelligence create in order to successfully distinguish this plane image from a helicopter, a bird or a kite? Can we add all the data? Or do we need to add it? Artificial intelligence engineers are constantly trying to tackle these questions.
So can the industry also make AI work with small data?
In fact, recent advances in artificial intelligence make this possible. Manufacturers can use the following techniques and technologies to overcome the small data problem to help AI projects come to life, even with only dozens or fewer samples:
Artificial data generationis used to synthesize new images that are difficult to collect in real life. Recent advances in techniques such as variable autoencoders, field randomization, and data augmentation can be used to do this.
transfer learningis a technique that allows AI to learn from a relevant task for which there is a sufficient amount of data, and then uses that information to help solve the small data task. For example, an AI learns to find dents from 1,000 dent images collected from various product and data sources. It can then transfer this information to detect dents on a particular new product with just a few images of dents.
Self-supervised learning: It is similar to transfer learning. But the information obtained is obtained by solving a slightly different task and then adapted to the small data problem. For example, you can take a large number of OK images and create a puzzle-like filter that will sort by underlying pattern. Solving this artificial problem will force the model to acquire domain knowledge that can be used as a starting point in a small data task.
In several-step learning, the problem of insufficient data is reformulated to help the AI system learn a control task that is easier, requiring less data, while achieving the same goal. In this scenario, the AI is given thousands of easier inspection tasks, with only 10 (or a similarly small number of) instances of each task. This forces the AI to learn to detect the most important patterns because it only has a small data set. From now on, when you expose this AI to the problem you care about, its performance with just a similar number of samples will benefit from having seen thousands of similar small data tasks.
One-stage learningis a special case of few-shot learning where the number of examples to learn per class is one instead of several (as in the example above).
In abnormality detection, AI sees zero defect instances and only instances of OK images. The algorithm learns to flag anything that deviates significantly from OK images as a potential problem.
hand coded information, is an example where an AI team meets with audit engineers and tries to encode as much of their enterprise knowledge into a system as possible. Modern machine learning is moving towards systems that rely on data rather than human knowledge, but when data isn't available, skilled AI teams can design machine learning systems that leverage that knowledge.
human in the loop, the techniques listed above can be used to generate more error examples. But the AI is smart enough to know when it trusts a label and when it doesn't, and knows to show that to a human expert and abide by their judgment in the latter case. Each time it does this, it also learns from the human, thus increasing accuracy and confidence in its output over time.
Using a combination of these approaches, manufacturers can create and deploy effective visual inspection models trained on at least 10 samples. Building systems with small data is important to overcome millions of use cases where only small data sets are available. For manufacturers, this minimizes the time, engineering effort, and data required to go live and create practical value from AI.